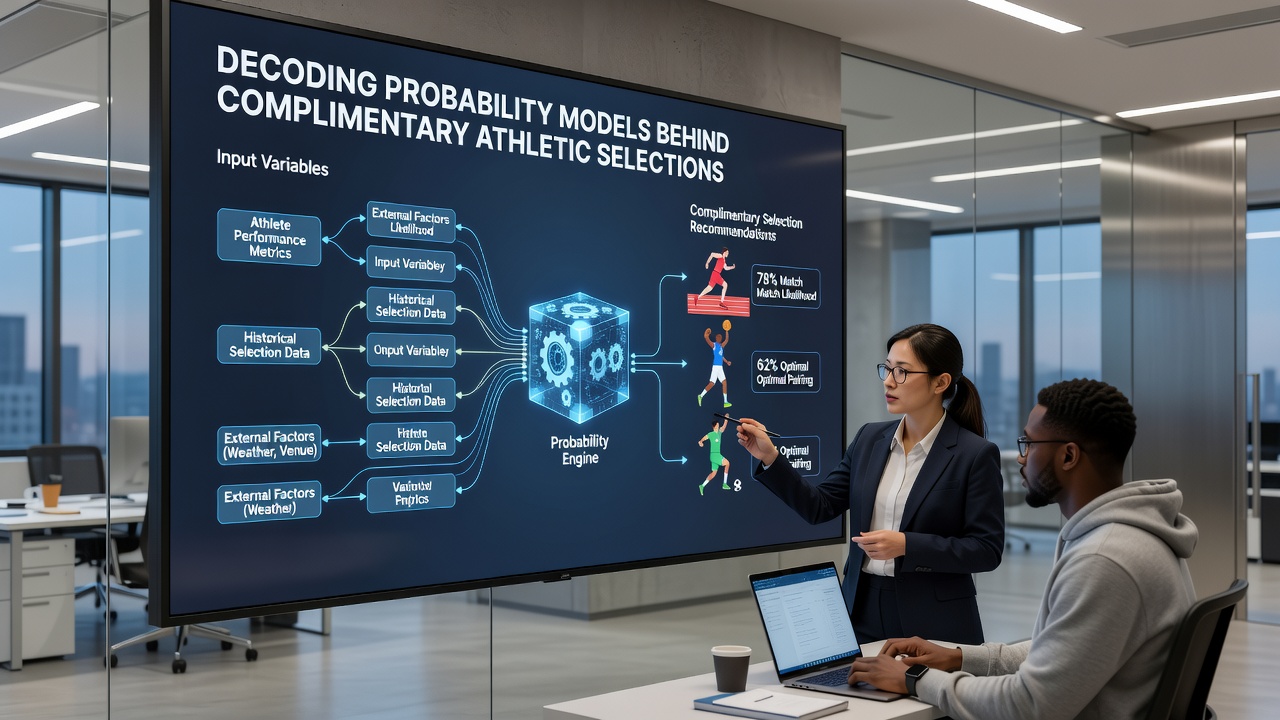
How Probability Models Shape Complimentary Athletic Selections
Complimentary athletic selections rely on structured probability models that convert raw performance data into predicted outcomes, and observers note these frameworks operate across multiple sports without requiring payment from users. Data from professional leagues shows teams generate thousands of data points per game, ranging from player speed metrics to historical matchup results, which feed directly into algorithmic calculations.
Core Components of These Models
Models typically begin with Bayesian inference techniques that update probabilities as new information arrives, while regression analysis identifies correlations between variables such as weather conditions and scoring rates. Researchers at institutions like the University of Sydney have documented how Poisson distributions help estimate goal counts in soccer by treating events as independent occurrences within fixed time intervals. And those who've examined large datasets find that Monte Carlo simulations run thousands of iterations to account for random variance, producing ranges rather than single-point predictions.
Key inputs include player injury reports, travel schedules, and recent form indicators, yet the integration process varies by sport because basketball emphasizes pace statistics whereas baseball focuses on pitch-specific data. Experts have observed that complementary selections often filter results through confidence thresholds, displaying only those picks where the calculated probability exceeds a predefined level, such as 55 percent.
Data Sources and Processing Steps
Public records from leagues and statistical agencies supply teh foundational datasets, and industry reports from organizations like the European Gaming and Betting Association highlight how standardized APIs pull live feeds during active seasons. Processing begins with data cleaning to remove outliers, followed by feature engineering that creates derived metrics such as adjusted efficiency ratings. Multiple models then run in parallel, with ensemble methods combining outputs to reduce individual model bias, according to findings published in sports analytics journals.
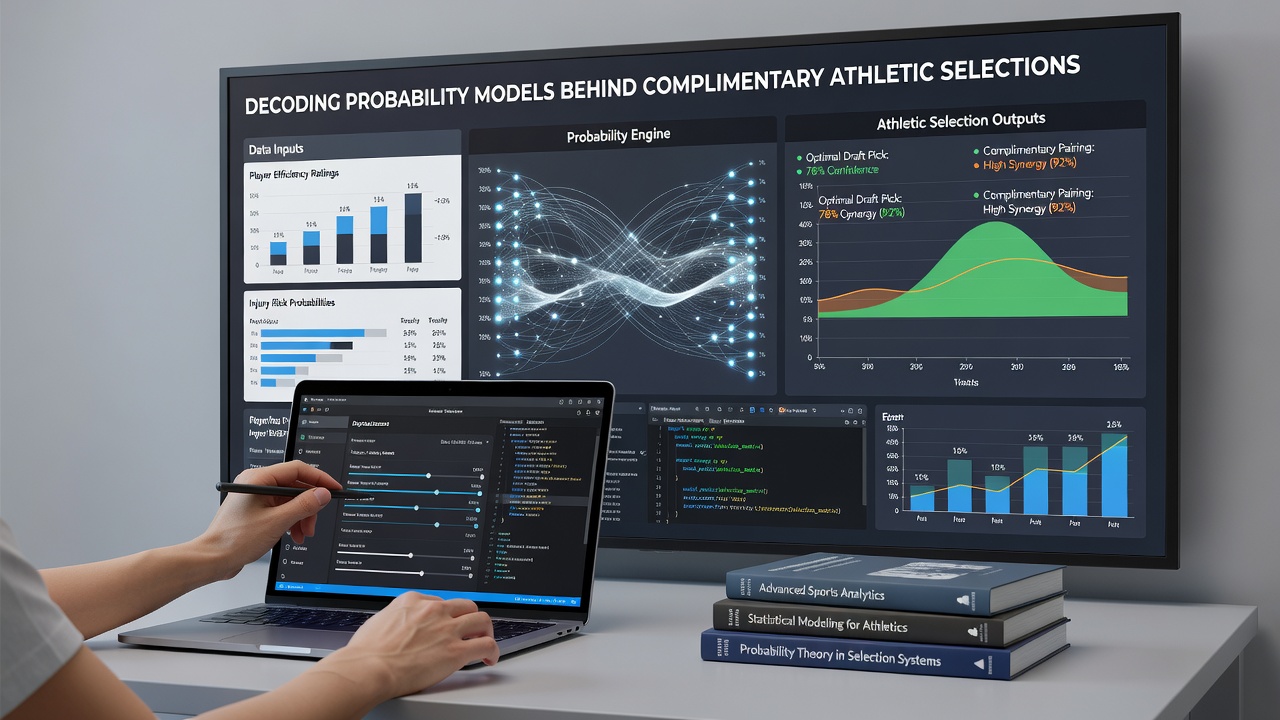
Validation occurs through backtesting against past seasons, where predicted probabilities are compared to actual results to measure calibration accuracy. Figures from the Australian Bureau of Statistics reveal that well-calibrated models maintain reliability across different competition levels, from amateur leagues to professional circuits, although performance can shift when rule changes alter game dynamics.
Seasonal Timing and September 2026 Context
September 2026 marks the start of several major leagues' schedules in North America and Europe, a period when model inputs undergo rapid updates due to roster changes and training camp results. Observers note that probability outputs for early-season selections often carry wider confidence intervals because historical data from the prior year carries less weight until new samples accumulate. Those monitoring these periods report increased computational demands as systems process both preseason metrics and opening-week results simultaneously.
Links to regulatory frameworks appear in jurisdictions such as the Malta Gaming Authority, which requires transparent disclosure of how complimentary selections derive from modeled probabilities, while Canadian provincial bodies have issued similar guidelines for information accuracy. One study from the University of Toronto examined how model transparency affects user trust levels across different demographic groups.
Limitations and Ongoing Adjustments
Even advanced models encounter constraints when unexpected events like mid-season trades or weather extremes disrupt expected patterns, and analysts adjust weighting schemes accordingly. Data indicates that recalibration happens at regular intervals, often weekly during active seasons, to maintain alignment with observed outcomes. People who've tracked model performance across multiple years find that ensemble approaches tend to outperform single-method systems, although no framework eliminates uncertainty entirely.
Conclusion
Probability models behind complimentary athletic selections continue to evolve through refined algorithms and expanded datasets, with September 2026 serving as a key checkpoint for new league cycles. External sources such as academic publications and regulatory reports provide ongoing benchmarks for accuracy, allowing these systems to deliver selections grounded in statistical methods rather than intuition alone. The process remains iterative, incorporating fresh evidence as each season progresses.