Statistical Modeling Techniques in Bookmaker Pricing for Specialized Events
Bookmakers apply a range of statistical modeling techniques when they set prices for niche events that draw limited public attention yet require precise risk management, and these methods combine historical data patterns with real-time adjustments to maintain balanced books across specialized markets such as obscure sports leagues, political outcomes, and entertainment awards. Researchers who examine betting industry practices note that models must account for sparse datasets because niche events rarely generate the volume of observations available in mainstream football or horse racing.
Foundational Distributions and Regression Approaches
Poisson distributions serve as a starting point for modeling count-based outcomes like goals or points scored in low-profile athletic contests, while logistic regression helps estimate binary results such as win or loss probabilities when direct head-to-head records remain thin. Observers note that these core techniques undergo calibration through maximum likelihood estimation, allowing operators to refine parameters even when sample sizes stay modest. Data from the Nevada Gaming Control Board indicates that operators routinely update these base models with Bayesian priors drawn from comparable events, which reduces variance in price outputs during periods of data scarcity.
Handling Data Limitations in Niche Markets
Niche event pricing demands extra layers of smoothing because standard frequentist methods falter when event histories span only a handful of occurrences, and practitioners therefore incorporate hierarchical models that borrow strength across related categories. For instance, one study revealed that multilevel Poisson regressions link performance metrics from minor tennis tournaments to broader player rankings, producing more stable implied probabilities than isolated calculations would allow. Those who monitor industry reports point out that shrinkage estimators play a key role here, pulling extreme estimates toward group averages and thereby limiting exposure on markets that attract uneven betting volume.
Machine Learning Integration and Simulation Methods
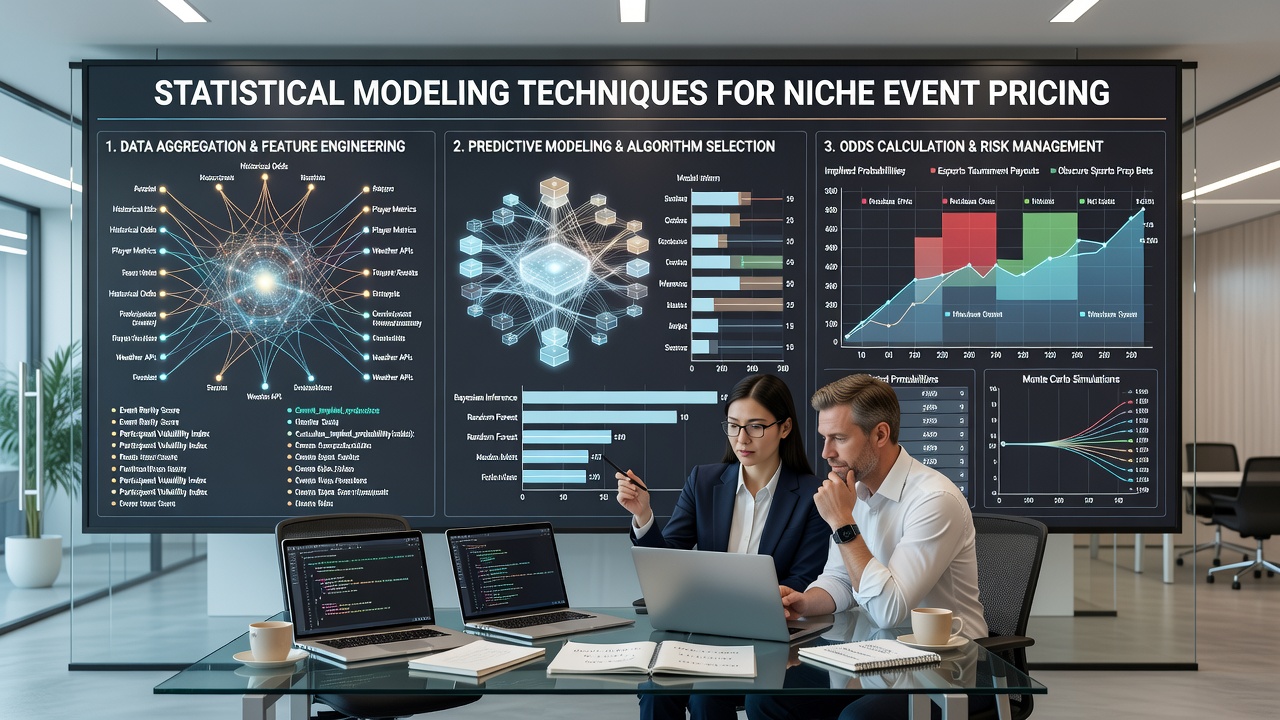
Random forests and gradient boosting machines now supplement traditional distributions by capturing nonlinear interactions among variables such as weather effects on niche outdoor competitions or social media sentiment around award ceremonies, and these ensemble approaches train on feature sets that include team travel schedules plus historical injury patterns. Monte Carlo simulations further enhance pricing accuracy by generating thousands of possible outcome paths for events like e-sports qualifiers where live data arrives in irregular bursts. Figures released in August 2026 from several North American operators show increased reliance on these hybrid systems, particularly as niche political betting markets expanded ahead of regional referendums.
Real-Time Adjustment and Risk Layering
Once initial prices reach the market, bookmakers overlay dynamic models that respond to incoming wagers and external signals, using techniques such as Kalman filters to track shifts in implied probabilities without overreacting to single large bets. This layering prevents rapid imbalances in niche segments where liquidity stays thin, and operators often combine these filters with copula functions that model joint distributions across correlated side markets. Evidence suggests that such integrated frameworks maintain margin targets even when individual events produce unexpected results, because the underlying statistical relationships account for tail risks that simpler models overlook.
Validation and Regulatory Context
Validation procedures rely on backtesting against archived results plus out-of-sample checks that measure calibration across multiple seasons, and academic researchers at institutions including the University of Sydney have published comparisons showing that properly tuned ensemble models outperform standalone regressions on low-frequency datasets. Regulatory frameworks in various jurisdictions require documentation of these validation steps to demonstrate that prices reflect genuine probability assessments rather than arbitrary margins, which encourages continued refinement of the underlying statistical infrastructure.
Conclusion
Statistical modeling techniques for niche event pricing therefore represent an evolving synthesis of classical distributions, hierarchical borrowing, machine learning ensembles, and real-time filtering that together address the unique constraints of sparse data environments. Operators continue to test new combinations of these tools as markets diversify, while external benchmarks from regulatory bodies and university studies provide reference points for ongoing calibration efforts.